LLMs与Prompt
简介
人工智能
从目的的角度出发,人工智能(AI)是人们创造的一些“聪明的”的算法,使得机器能够像人类一样“思考”。这些算法可以写论文、解决数学问题,并创造艺术。该领域的最新进展已经十分先进,以至于人工智能可以写出令人信服的销售邮件、新闻报道,甚至可以赢得艺术比赛。
目前,人工智能正在颠覆许多行业,包括新闻行业、医疗卫生行业和教育行业。你可能很快看到人工智能在你工作或教学中出现,即使现在还没有。但是,尽管人工智能非常有用,但它们需要人类来指导它们做什么。通常情况下,人工智能就像非常聪明的小孩。它们可以做很多事情,但它们需要仔细的指导才能做得好。
大型语言模型(LLMs)
大型语言模型(Large Language Models,简称LLMs)是一类基于深度学习的人工智能模型。它们是由海量的数据和大量的计算资源训练而成的,可以理解和生成自然语言。其中,最著名的 LLM 代表之一是 OpenAI 开发的 GPT-4(Generative Pre-trained Transformer 4),该模型拥有数十亿个参数,使得其在自然语言处理任务上表现非常出色。
而在 LLMs(Large Language Models,大型语言模型)的开发中,大致可分为两种类型:基础 LLM 和指令调谐 LLM 。基础 LLM(Base LLM) 的特点是基于大量文本训练数据,来预测下一个最有可能出现的单词,缺点是不可控,容易输出有问题的文本。相比之下,指令调谐 LLM(Instruction Tuned LLM) 则是在基础 LLM 之上再经过了人工的微调,因此能够更好地遵循指令来输出有用的内容。大多数人应更专注于后者,因为它们更容易使用,也更安全、更一致,本教程的内容也主要是围绕后者的相关实践。
Prompt
什么是Prompt Engineering
解释这个词之前,首先需要解释 Prompt 这个词,简单的理解它是给 AI 模型的指令,它可以是一个问题、一段文字描述,甚至可以是带有一堆参数的文字描述。AI 模型会基于 Prompt 所提供的信息,生成对应的文本,亦或者图片。
比如,我们在 ChatGPT 里输入What is the capital of China?(中国的首都是什么?),这个问题就是 Prompt:
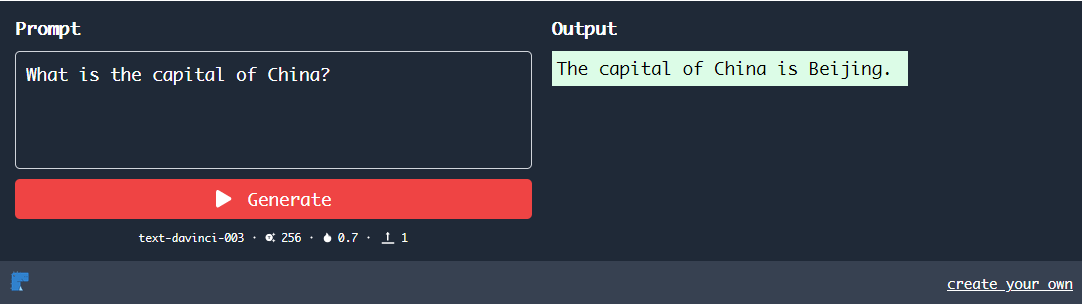
而 Prompt Engineering(中文意思为提示工程,后缩写为 PE)被解释为:Prompt Engineering 是一种人工智能(AI)技术,它通过设计和改进 AI 的 prompt 来提高 AI 的表现。Prompt Engineering 的目标是创建高度有效和可控的 AI 系统,使其能够准确、可靠地执行特定任务。
简单说来就是你可能用过不少 AI 相关的产品,你或许会觉得好像只需要会说话、会打字,就能让 AI 输出答案。好像不需要什么技术。的确,如果你只想让 AI 给你答案,你不需要额外做什么,只需要输入文字即可。但如果你想要得到满意的答案,甚至精确的答案。就需要用到 PE 这个技术。
因为人类的语言从根本上说是不精确的,目前机器还没法很好地理解人类说的话,所以才会出现 PE 这个技术。另外,受制于目前大语言模型 AI 的实现原理,部分逻辑运算问题,需要额外对 AI 进行提示。
举个例子,如果我们在 ChatGPT 里输入这样的一段话:
What is 100*100/400*56?
ChatGPT 会返回一个错误的答案 0.4464(旧版的模型 API):
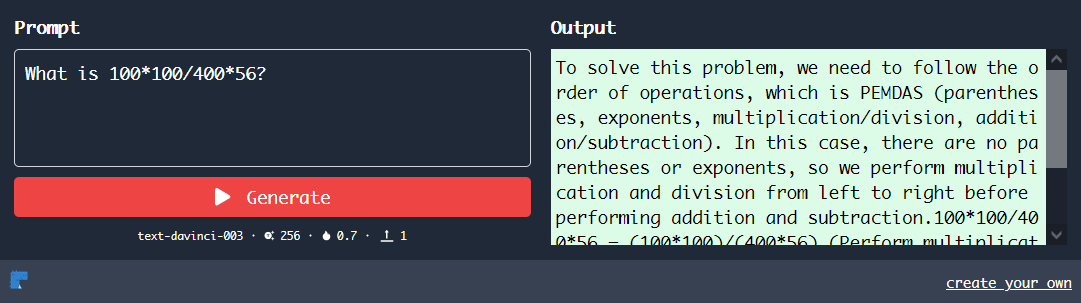
但如果我们对 Prompt 进行一些修改,答案则会是正确的:
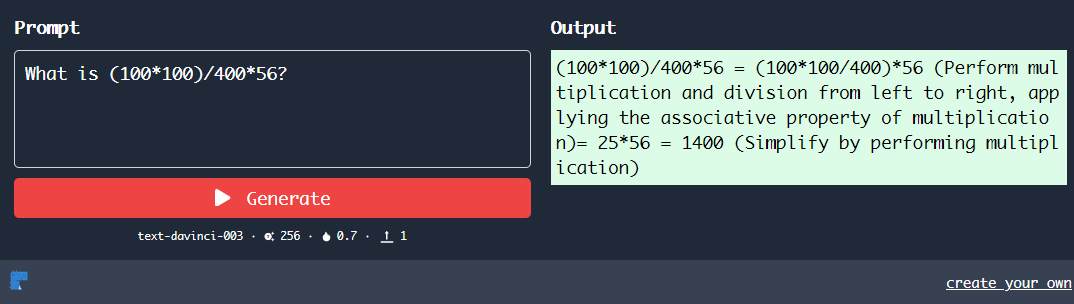
所以,总的来说,Prompt Engineering 是一种重要的 AI 技术:
- 如果你是 AI 产品用户,可以通过这个技术,充分发挥 AI 产品的能力,获得更好的体验,从而提高工作效率。
- 如果你是产品设计师,或者研发人员,你可以通过它来设计和改进 AI 系统的提示,从而提高 AI 系统的性能和准确性,为用户带来更好的 AI 体验。
需要学习 PE 吗
坦率说来,大家对 PE 有一些争议。前面一节主要介绍了 Prompt 的各种好处。但也有人认为这个就像当年搜索工具刚出来的时候,出现了不少所谓的「搜索专家」,熟练使用各种搜索相关的奇技淫巧,但现在这些专家都不存在了。因为产品会不断迭代,变得更加易用,无需再使用这些技巧。
拿前面提到的数学问题为例,API 版本算出来是 14,但 ChatGPT 的版本则看上去更准确一些,相信不久的将来,我们无需在公式前加括号,它就能返回正确的结。
但综合我对产品和用户的理解,以及各位专家学者的看法,我的个人理解是:现在 AI 的发展还比较早期,了解和学习 PE 价值相对比较大,但长远来看可能会被淘汰。这个「长远」可能是 3 年,亦或者 1 年。
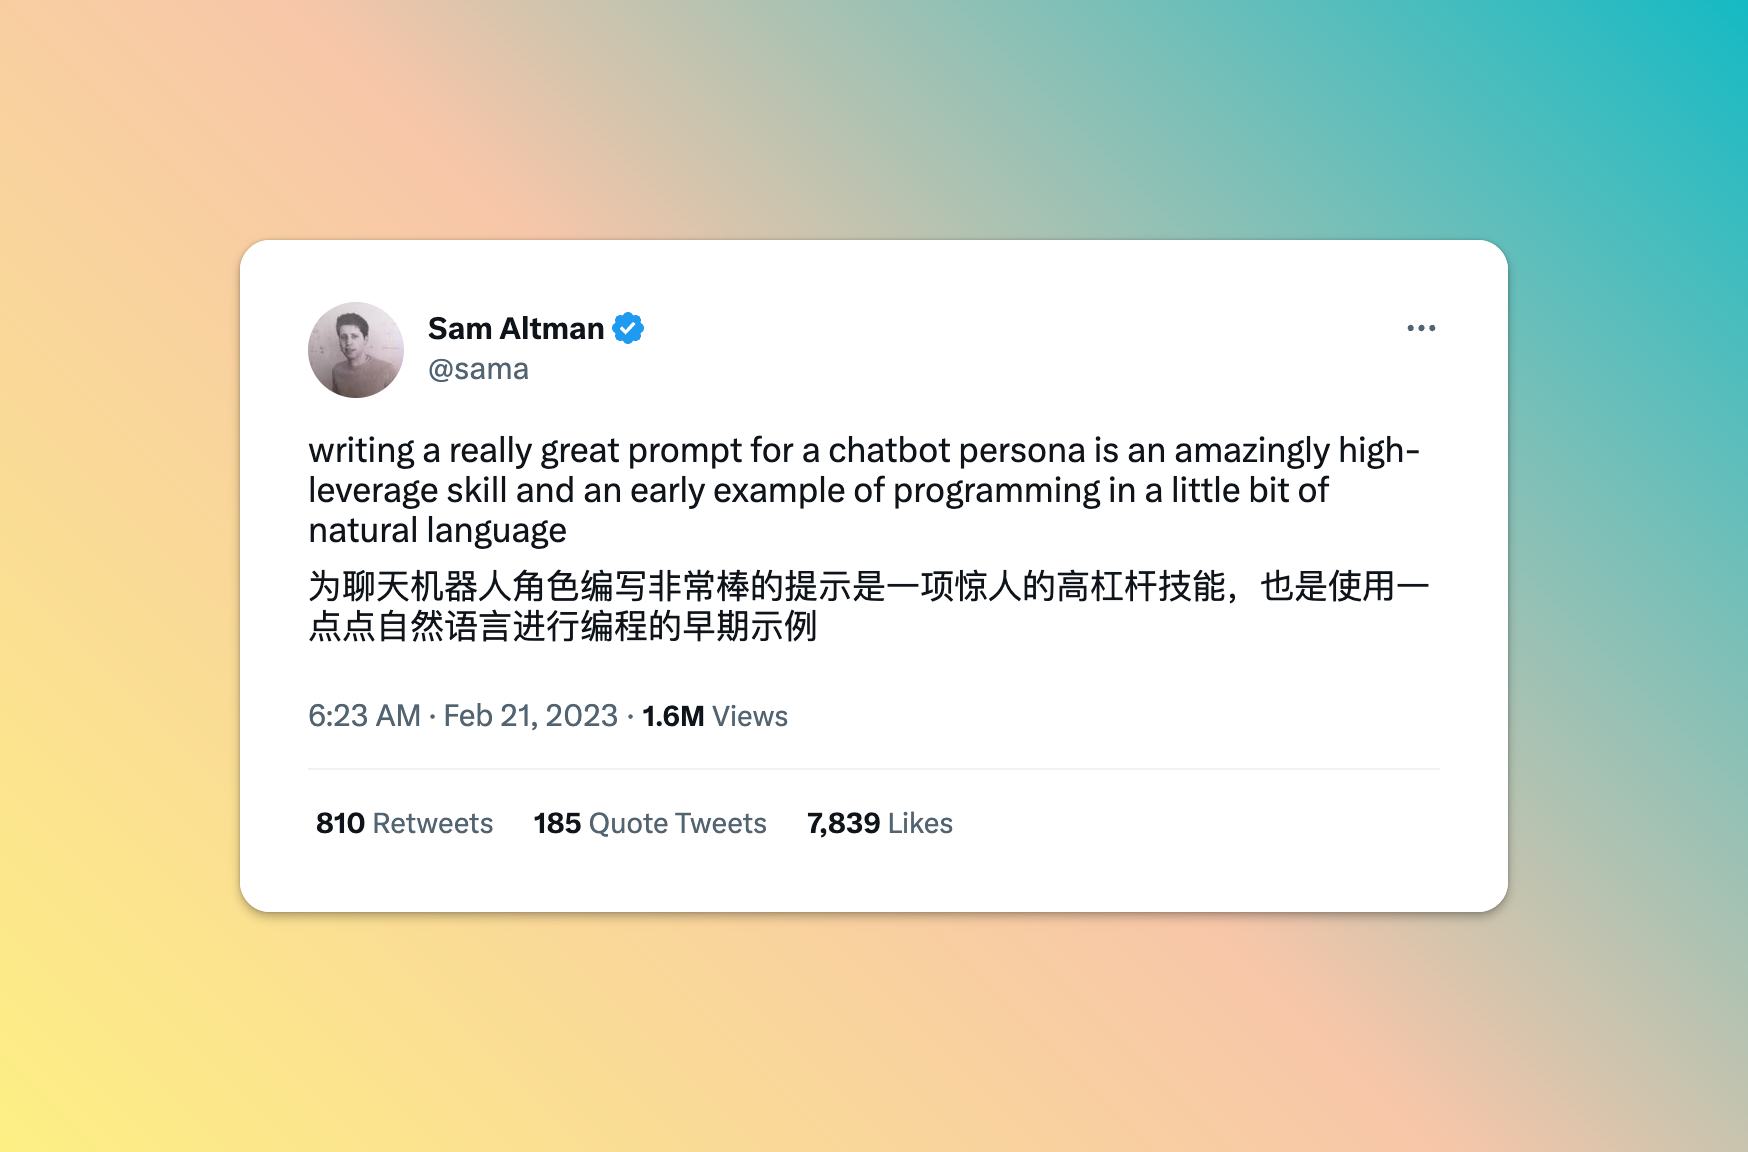
OpenAI 的 CEO Sam Altman 在今年 2 月底提到给 ChatBot 写 Prompt 是个非常高杠杆的技能:
但如果你看过 Sam Altman 去年的访谈,他在去年 9 月的时候就提过,5 年内我们很可能就不再需要 PE:
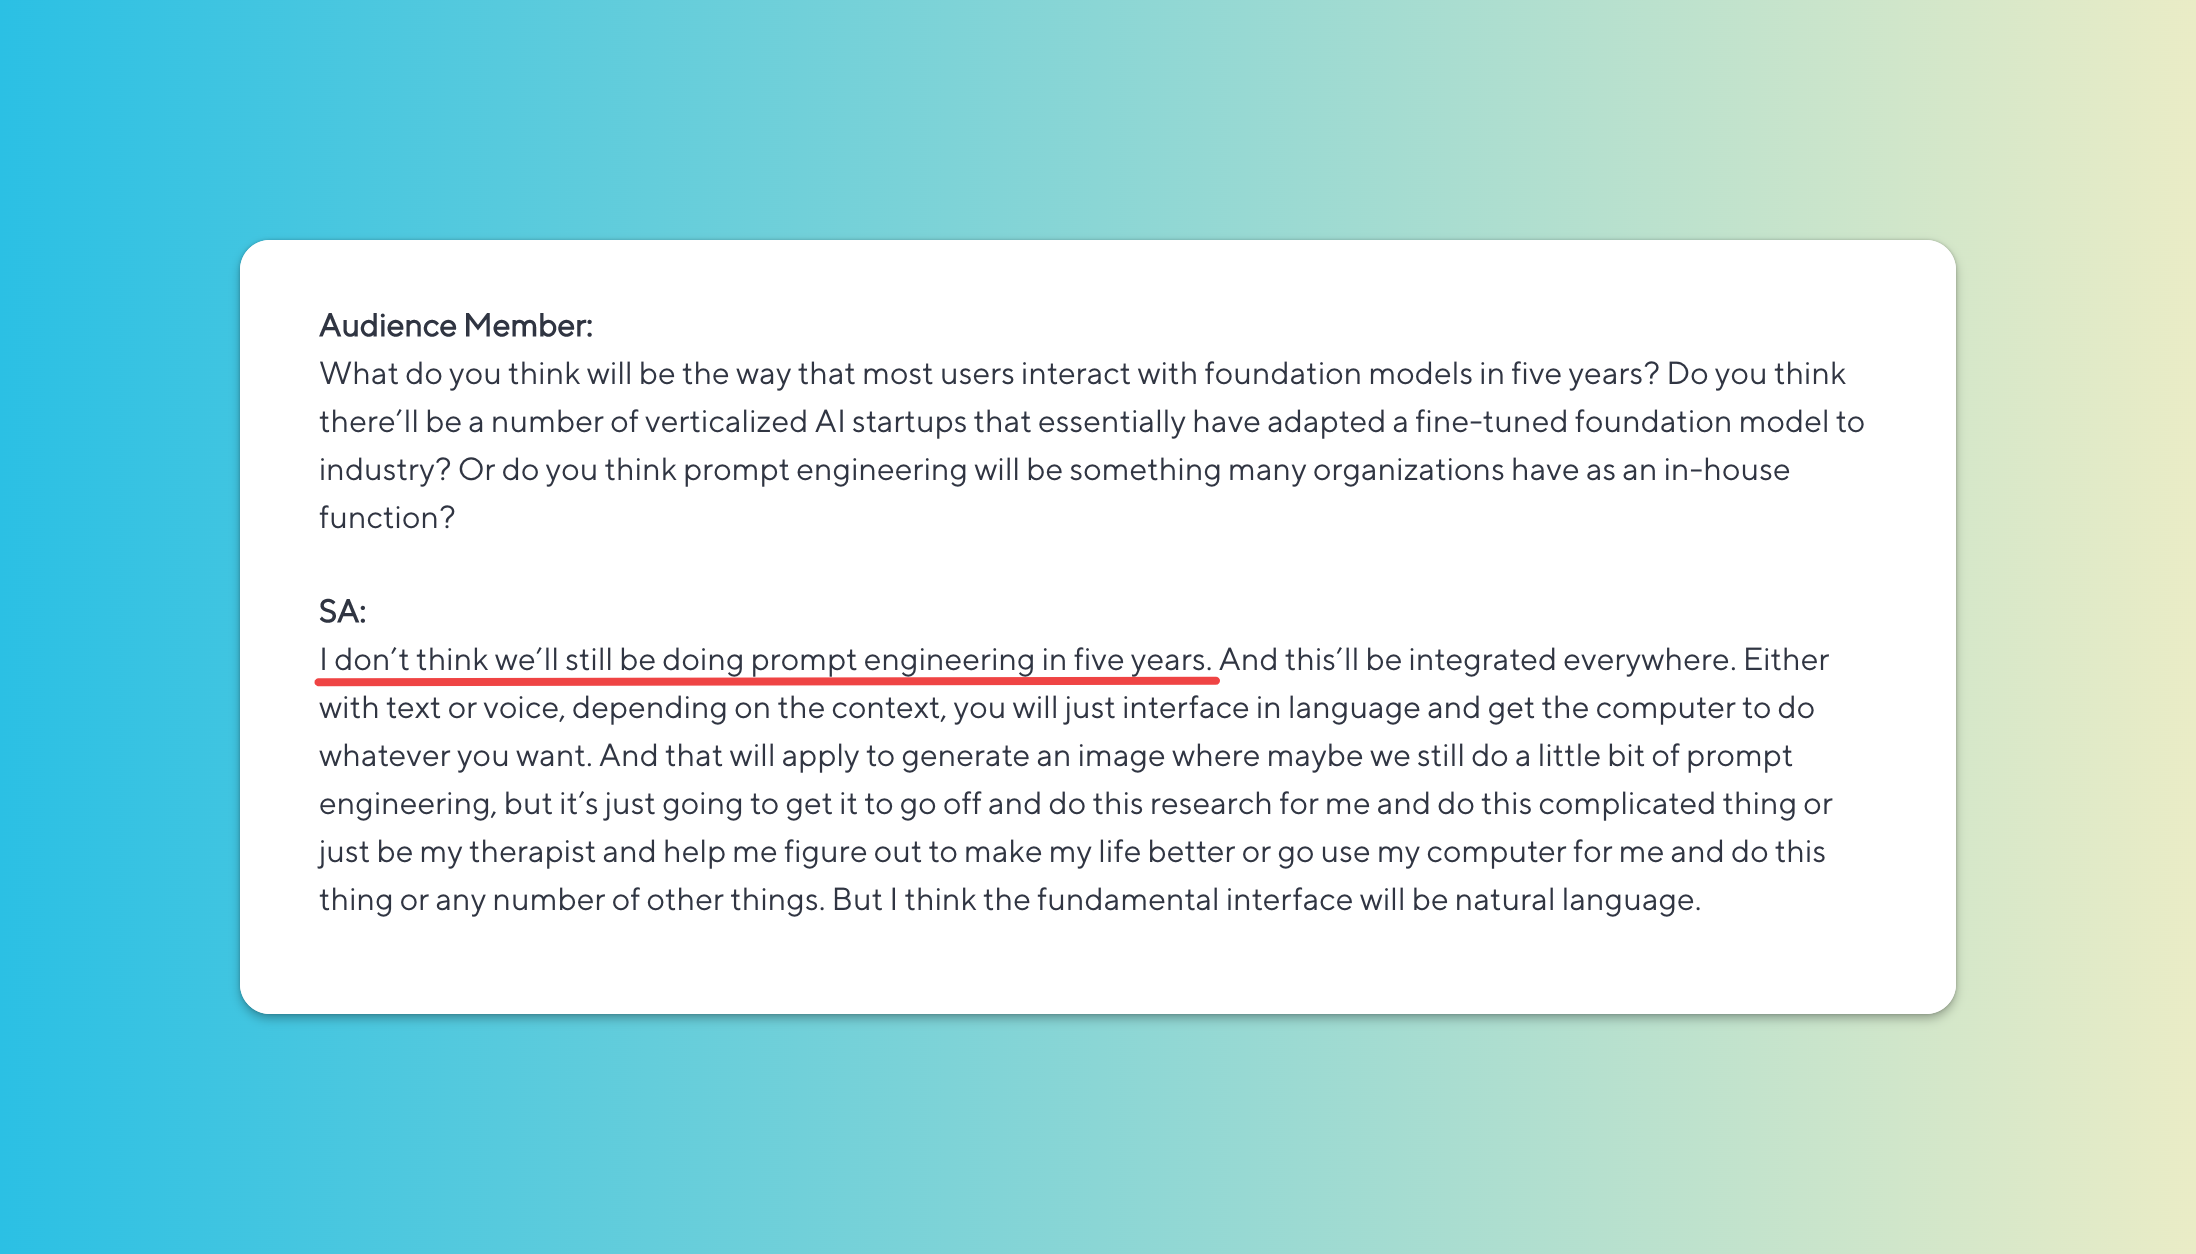
从用户的角度看,我认为学习 Prompt 可以让你更好地使用 ChatGPT 等产品。
从产品的角度看,对于用户来说,我认为 Prompt 会是个短期过度形态,未来肯定会有更友好的交互形式,或者理解能力更强的 AI 产品。
One More Thing
介于 ChatGPT 是目前最火的 LLM,本教程使用 ChatGPT 做为 Prompt 及五大工种示例的 LLM。
此外 ChatGPT 是一种基于英语语言模型的技术,因此在英语环境中使用它可以获得更好的性能和结果。虽然它可以处理多种语言,但在处理非英语语言时,它可能会遇到语言结构、词汇和语法方面的挑战,从而影响其表现。大多数 ChatGPT 模型的训练数据是英语文本,因此如果使用中文或其他非英语语言,模型可能需要更多的数据来提高其表现。
如果您使用ChatGPT进行英语文本的自然语言处理任务,使用英语可能会更有效。但如果您需要处理非英语文本,使用对应的语言可能会更好,因此于 Prompt 而言,英文能更准确进行相关示例,本章节将全部使用英文进行提问。
最后由于本教程使用 AIPRM 插件,无需额外学习 Prompt,以下内容可直接跳过,若有兴趣可以继续查阅本章节,本章节只简单介绍 ChatGPT 与 Prompt 部分基础内容,深入学习建议查阅吴恩达教授联合 OpenAI 制作的经典教程《面向开发者的ChatGPT提示工程》。
Prompt 基本原则
在和 ChatGPT 对话时,亦或者在使用和设计 Prompt 时,有以下几个原则与建议,记住这几个原则,能让你写出更好的 Prompt。
原则一:建议使用最新的模型
如果你是直接使用 AI 产品,比如 ChatGPT 或者 Midjourney,那无需在意这个原则。如果你是通过 API 或者 OpenAI Playground 的方式使用,则建议你先使用最新的模型测试。
原则二:Prompt 里最好包含完整的信息
这个是对结果影响最大的因素。
比如如果你想让 AI 写一首关于 OpenAI 的诗。
Write a poem about OpenAI.
它生成的答案可能就会很宽泛,而更好的方式是增加更多的信息。
Write a short inspiring poem about OpenAI, focusing on the recent DALL-E product launch (DALL-E is a text to image ML model) in the style of a {famous poet}
原则三:Prompt 最好简洁易懂,并减少歧义
这个比较好理解,即使你跟人说话,说一些简单的短句,对方也会更容易听懂,AI 也是这样。另外,在 Prompt 里也需要减少一些歧义,少用模棱两可的词语。
比如像这个就很不明确,什么叫 not too much more?
The description for this product should be fairly short, a few sentences only, and not too much more.
更好的 Prompt 是这样的,明确告知要写多少句话,就比较明确:
Use a 3 to 5 sentence paragraph to describe this product.
另外需要注意的是,简单并不代表简短。你的 Prompt 也可以很长,只要你的 Prompt 描述更充分就可以,即使长一点也没有关系。
原则四:Prompt 要使用正确的语法、拼写,以及标点
特别是在使用英语的 Prompt 的时候,一定要注意语法和拼写。
原则五:从简单的先开始,并给产品多一点耐心
最后一点算是我个人的建议。如前面提到的例子What is 100*100/40*56?一样,如果发现机器理解错误,不妨补充点信息,不妨多实验几次,给 AI 多一点耐心。
Prompt 基本使用场景
场景1:问答问题
这个场景应该是使用 AI 产品最常见的方法,以 ChatGPT 为例,一般就是你提一个问题,ChatGPT 会给你答案,如下:

这种直接提问的 Prompt ,我们称之为 Zero-shot Prompt。模型基于一些通用的先验知识或模型在先前的训练中学习到的模式,对新的任务或领域进行推理和预测。在这个场景下,Prompt 只要满足前面提到的基本原则,基本上就没有什么问题。但需要注意,不同的 AI 模型擅长的东西都不太一样,Prompt 可能需要针对该模型进行微调。另外,目前的 AI 产品,也不是无所不能,有些问题你再怎么优化 Prompt 它也没法回答你。以 ChatGPT 为例:
- ChatGPT 比较擅长回答基本事实的问题,比如问
什么是牛顿第三定律?。但不太擅长回答意见类的问题,比如问它谁是世界第一足球运动员?,它就没法回答了。 - 另外,ChatGPT 的数据仅有 2021 年 9 月以前的(老版本 API),如果你问这个时间以后的问题,比如
现在的美国总统是谁?它的答案是截至2021年9月,现任美国总统是乔·拜登(Joe Biden)。
此外,问答场景里还有一个很重要的玩法,就是多轮聊天,你可以针对某个问题,进行多轮的提问。
场景2:基于示例回答
在某些场景下,我们能比较简单地向 AI 描述出什么能做,什么不能做。但有些场景,有些需求很难通过文字指令传递给 AI,即使描述出来了,AI 也不能很好地理解。
比如给宠物起英文名,里面会夹杂着一些所谓的名字风格。此时你就可以在 Prompt 里增加一些例子,我们看看这个例子。
这个是没有任何示例的 Prompt:
Suggest three names for a horse that is a superhero.
Output 如下所示。第一个感觉还行,第二个 Captain 有 hero 的感觉,但 Canter 就像是说这匹马跑得很慢,感觉不太合适,而且三个都比较一般,不够酷。
Thunder Hooves, Captain Canter, Mighty Gallop
场景3:推理
在问答这个大场景下,还有一个子场景是推理,这个场景非常有意思,而且是个非常值得深挖的场景,Prompt 在此场景里发挥的作用非常大。如果你想用 ChatGPT API 做点什么小应用,我建议可以从这个场景入手。
举个比较简单的例子,我将美国工商管理硕士的入学考试 GMAT 的一道数学题输入进了 ChatGPT:
If a real estate agent received a commission of 6 percent of the selling price of a certain house, what was the selling price of the house?
(1) The selling price minus the real estate agent’s commission was $84,600.
(2) The selling price was 250 percent of the original purchase price of $36,000.

(A) Statement (1) ALONE is sufficient, but statement (2) alone is not sufficient.
(B) Statement (2) ALONE is sufficient, but statement (1) alone is not sufficient.
(C) BOTH statements TOGETHER are sufficient, but NEITHER statement ALONE is sufficient.
(D) EACH statement ALONE is sufficient.
(E) Statements (1) and (2) TOGETHER are NOT sufficient.
这道题目的中文意思是这样的:
如果一个房地产经纪人的佣金是某个房子的售价的6%,那么这个房子的售价是多少?
(1)售价减去房地产经纪人的佣金为84,600美元。
(2)购买价是36,000美元,售价是购买价的250%。

(A)仅陈述(1)足以回答问题,但仅陈述(2)不能回答问题。
(B)仅陈述(2)足以回答问题,但仅陈述(1)不能回答问题。
(C)两个陈述合起来足以回答问题,但没有一个陈述单独足以回答问题。
(D)每个陈述单独足以回答问题。
(E)陈述(1)和(2)合起来不能回答问题。
它的 Output 是这样的,它会根据题目的要求去推理和运算:
Let's assume the selling price of the house is S.
According to the given information, the real estate agent's commission is 6% of S, which is 0.06S.
So, the amount received by the seller after paying the commission would be (S - 0.06S) = 0.94S.
Statement (1) tells us that 0.94S = $84,600. Solving for S, we get S = $90,000.
Therefore, statement (1) alone is sufficient to determine the selling price of the house.
Statement (2) tells us that the selling price is 250% of the original purchase price, which means S = 2.5*$36,000 = $90,000.
Therefore, statement (2) alone is also sufficient to determine the selling price of the house.
Since both statements individually provide the same answer, we can conclude that together they are also sufficient to determine the selling price of the house.
Hence, the answer is (D) EACH statement ALONE is sufficient.
翻译成中文是这样的:
假设房子的售价为S。
根据所给信息,房地产经纪人的佣金是S的6%,即0.06S。
因此,在支付佣金后卖方收到的金额为(S-0.06S)= 0.94S。
陈述(1)告诉我们,0.94S = 84,600美元。解出S,我们得到S = $90,000。
因此,陈述(1)单独足以确定房子的售价。
陈述(2)告诉我们,售价是原始购买价的250%,这意味着S = 2.5 * $36,000 = $90,000。
因此,陈述(2)单独也足以确定房子的售价。
由于两个陈述分别提供相同的答案,我们可以得出结论,它们共同足以确定房子的售价。
因此,答案是(D)每个陈述单独足以回答问题。
这个场景还比较简单,此处就不进行更多示例了,你可以将各种题目输入进 ChatGPT 里试试。
场景4:无中生有——写代码
除了回答问题外,另一个重要的场景是让 AI 根据你的要求完成一些内容生成任务,根据输出的结果差异,我将其概括为以下几个主要场景:
- 无中生有
- 锦上添花
- 化繁为简
本场景,我们先来聊聊「无中生有」场景。顾名思义,就是让 AI 给你生成一些内容。你只需要向 AI 描述你想写的内容,AI 就会按你的要求写出该内容。比如:
- 撰写招聘信息
- 撰写电商平台的货物描述
- 撰写短视频脚本
- 编写代码
像撰写招聘信息等,你只需要明确目标,将目标定得比较明确即可生成能让你较为满意的答案。此处进行一个代码示例:
Prompt:
Create a MySQL query for all students in the Computer Science Department:
Table departments, columns = [DepartmentId, DepartmentName]
Table students, columns = [DepartmentId, StudentId, StudentName]
Output:
SELECT students.*
FROM students
INNER JOIN departments
ON students.DepartmentId = departments.DepartmentId
WHERE departments.DepartmentName = 'Computer Science';
场景5:锦上添花——改写内容
除了从 0 生成内容外,你也可以先给 AI 一段已经写好的内容,然后让 AI 对其进行修改,让 AI 帮你将内容改得更好。实际的场景有如:
- 翻译:将中文文档翻译成英文,亦或者将英文翻译成中文。关于翻译,我还想强调,像 ChatGPT 除了能翻译人类的语言外,还能翻译编程语言,比如将 Python 代码翻译成 Haskell 代码。
- 修改:修改内容的语法,甄别内容里的错别字。
- 润色:润色文章,将内容改成另一种风格。
此处重点介绍下润色场景,下面这是个润色的例子。
Prompt(内容来自维基百科):
Please rewrite the following sentences to make them easier to understand.
OpenAI is an American artificial intelligence (AI) research laboratory consisting of the non-profit OpenAI Incorporated (OpenAI Inc.) and its for-profit subsidiary corporation OpenAI Limited Partnership (OpenAI LP). OpenAI conducts AI research with the declared intention of promoting and developing a friendly AI. OpenAI systems run on the fifth most powerful supercomputer in the world.[5][6][7] The organization was founded in San Francisco in 2015 by Sam Altman, Reid Hoffman, Jessica Livingston, Elon Musk, Ilya Sutskever, Peter Thiel and others,[8][1][9] who collectively pledged US$1 billion. Musk resigned from the board in 2018 but remained a donor. Microsoft provided OpenAI LP with a $1 billion investment in 2019 and a second multi-year investment in January 2023, reported to be $10 billion.[10]
它的 Output 是这样的:
OpenAI is a research organization that focuses on artificial intelligence (AI). It has two parts: a non-profit called OpenAI Incorporated and a for-profit subsidiary called OpenAI Limited Partnership. The organization's goal is to create AI that is friendly and beneficial to humans. OpenAI uses one of the most powerful supercomputers in the world for its research. The organization was founded in San Francisco in 2015 by a group of people who pledged a total of $1 billion, including Sam Altman, Reid Hoffman, Jessica Livingston, Elon Musk, Ilya Sutskever, and Peter Thiel. Musk resigned from the board in 2018 but still supports the organization financially. In 2019, Microsoft invested $1 billion in OpenAI LP, and in January 2023, they made a second investment reported to be $10 billion.
场景6:锦上添花——信息解释
锦上添花下的第二大的场景是信息解释。它跟改写内容有点像,但又不太一样,信息解释有可能提供超过原文内容的信息。
举几个信息解释的例子,大家应该就能理解了:
- 解释代码:比如你看到一段 Python 的代码,但你看不懂,你可以让 AI 解释下代码的含义。
- 解释论文:看某篇论文看不懂,或者论文里的某一段看不懂,你也可以让 AI 解释。
以解释代码为例,它的 Prompt 是这样的(此案例来自 OpenAI 官方案例):
Explanation of what the code does:

Python 3
def remove_common_prefix(x, prefix, ws_prefix):
    x["completion"] = x["completion"].str[len(prefix) :]
    if ws_prefix:
        # keep the single whitespace as prefix
        x["completion"] = " " + x["completion"]
return x
以下是 ChatGPT 的 Output,它阐述了这段代码是拿来干什么的,同时还阐述了各个参数的含义:
This is a Python function called remove_common_prefix that takes in three parameters: x, prefix, and ws_prefix.
The x parameter is assumed to be a Pandas DataFrame or Series object with a column named "completion", which contains strings that may or may not start with the prefix string.
The prefix parameter is a string that represents the common prefix that needs to be removed from the beginning of each string in the "completion" column of the DataFrame.
The ws_prefix parameter is a Boolean value that indicates whether or not to keep a single whitespace character as a prefix after the common prefix has been removed.
The function modifies the "completion" column of the DataFrame by removing the prefix string from the beginning of each string in that column using the Pandas str method and string slicing. The len(prefix) : syntax is used to slice the string starting from the character that follows the prefix.
If ws_prefix is True, then the function adds a single whitespace character as a prefix to each string in the "completion" column after removing the prefix.
Finally, the modified DataFrame is returned by the function.
场景7:化繁为简——信息总结
内容生成大场景下的第二个场景是化繁为简,这个场景其实很好理解,就是将复杂的内容,转为简单的内容,一般常遇到的场景有:
- 信息总结:顾名思义,就是对一堆信息进行总结。
- 信息解释:这个跟改写内容有点像,但这个更偏向于解释与总结。下一章会给大家介绍更多的例子。
- 信息提取:提取信息里的某一段内容,比如从一大段文字中,找到关键内容,并分类。
此处简单讲一下信息总结。信息总结还是比较简单的,基本上在 Prompt 里加入总结 summarize 就可以了。但如果你想要一些特别的效果,不妨组合下列章节的技巧,比如:
- 使用技巧2:增加示例,让 AI 总结符合你需求的内容
- 使用#技巧4:增加-role(角色)或人物,让 AI 总结的内容具有一定的风格
场景8:化繁为简——信息提取
介绍完信息总结,再聊聊信息提取,我认为这个场景是继场景3 推理以外,第二个值得深挖的场景。这个场景有非常多的有意思的场景,比如:
- 将一大段文字,甚至网页里的内容,按要求转为一个表格。按照这个思路你可以尝试做一个更智能的,更易懂的爬虫插件。
- 按照特定格式对文章内容进行信息归类。
第二个可能比较难理解,举个 OpenAI 里的例子,它的 Prompt 是这样的(为了有足够空间显示内容,我仅节选了 text 里的部分内容):
Extract the important entities mentioned in the article below. First extract all company names, then extract all people names, then extract specific topics which fit the content and finally extract general overarching themes
Desired format:
Company names: <comma_separated_list_of_company_names>
People names: -||-
Specific topics: -||-
General themes: -||-

Text: """Powering Next Generation
Applications with OpenAI Codex
Codex is now powering 70 different applications across a variety of use cases through the OpenAI API.

May 24, 2022
4 minute read
OpenAI Codex, a natural language-to-code system based on GPT-3, helps turn simple English instructions into over a dozen popular coding languages. Codex was released last August through our API and is the principal building block of GitHub Copilot.
Warp is a Rust-based terminal, reimagined from the ground up to help both individuals and teams be more productive in the command-line.
Terminal commands are typically difficult to remember, find and construct. Users often have to leave the terminal and search the web for answers and even then the results might not give them the right command to execute. Warp uses Codex to allow users to run a natural language command to search directly from within the terminal and get a result they can immediately use.
“Codex allows Warp to make the terminal more accessible and powerful. Developers search for entire commands using natural language rather than trying to remember them or assemble them piecemeal. Codex-powered command search has become one of our game changing features.”
—Zach Lloyd, Founder, Warp


Machinet helps professional Java developers write quality code by using Codex to generate intelligent unit test templates.
Machinet was able to accelerate their development several-fold by switching from building their own machine learning systems to using Codex. The flexibility of Codex allows for the ability to easily add new features and capabilities saving their users time and helping them be more productive.
“Codex is an amazing tool in our arsenal. Not only does it allow us to generate more meaningful code, but it has also helped us find a new design of product architecture and got us out of a local maximum.”
—Vladislav Yanchenko, Founder, Machinet"""
```html

Prompt 有点长,总的来说,它是让 AI 将文章里的重点内容进行抽离,并将其根据特定格式进行输出。要求将文章里提到的公司、人名、主题都按照 comma separated list(按逗号空格分开)的方式罗列出来。

最后的 output 是这样的:
```html
Company names: OpenAI, Microsoft, GitHub, Pygma, Replit, Warp, Machinet
People names: Emile Paffard-Wray, Amjad Masad, Zach Lloyd, Vladislav Yanchenko
Specific topics: GPT-3, OpenAI API, Azure OpenAI Service, GitHub Copilot, Pygma, Replit, Warp, Machinet
General themes: Natural language-to-code, Productivity, Problem solving, Creativity, Learning
Prompt 基本技巧
技巧1:To Do and Not To Do
结合场景1:问答问题,为了让 AI 回答更加准确,一般会在问题里加条件。比如让 AI 推荐一部电影给你Recommend a movie to me。但这个 Prompt 太空泛了,AI 无法直接回答,接着它会问你想要什么类型的电影,但这样你就需要跟 AI 聊很多轮,效率比较低。
所以,为了提高效率,一般会在 Prompt 里看到类似这样的话(意思是不要询问我对什么感兴趣,或者问我的个人信息):
DO NOT ASK FOR INTERESTS. DO NOT ASK FOR PERSONAL INFORMATION.
如果你在 ChatGPT 里这样提问,或者使用 ChatGPT 最新的 API ,它就不会问你问题,而是直接推荐一部电影给你,它的 Output 是这样的:
Certainly! If you're in the mood for an action-packed movie, you might enjoy "John Wick" (2014), directed by Chad Stahelski and starring Keanu Reeves. The movie follows a retired hitman named John Wick who seeks vengeance against the people who wronged him. It's a fast-paced and stylish film with lots of thrilling action sequences and an engaging story. If you're looking for something that will keep you on the edge of your seat, "John Wick" is definitely worth a watch!
但如果你使用的是如 Davinci-003 这样的模型,它的 Output 很可能是这样的,它还会问你的兴趣爱好:
Sure, I can recommend a movie based on your interests. What kind of movie would you like to watch? Do you prefer action, comedy, romance, or something else?
所以 OpenAI 的 API 最佳实践文档里,提到了一个这样的最佳实践:
- Instead of just saying what not to do, say what to do instead. 与其告知模型不能干什么,不妨告诉模型能干什么。
我自己的实践是,虽然现在最新的模型已经理解什么是 Not Todo ,但如果你想要的是明确的答案,加入更多限定词,告知模型能干什么,回答的效率会更高,且预期会更明确。还是电影推荐这个案例,你可以加入一个限定词:
Recommend a movie from the top global trending movies to me.
当然并不是 Not Todo 就不能用,如果:
- 你已经告知模型很明确的点,然后你想缩小范围,那增加一些 Not Todo 会提高不少效率。
- 你是在做一些探索,比如你不知道如何做精准限定,你只知道不要什么。那可以先加入 Not Todo ,让 AI 先发散给你答案,当探索完成后,再去优化 Prompt。
以下是一些场景案例,我整理了两个 Less Effective(不太有效的) 和 Better(更好的) Prompt,你可以自己尝试下这些案例:
| 场景 | Less Effective | Better | 原因 |
|---|---|---|---|
| 推荐雅思必背英文单词 | Please suggest me some essential words for IELTS | Please suggest me 10 essential words for IELTS | 后者 Prompt 会更加明确,前者会给大概 20 个单词。这个仍然有提升的空间,比如增加更多的限定词语,像字母 A 开头的词语。 |
| 推荐香港值得游玩的地方 | Please recommend me some places to visit in Hong Kong. Do not recommend museums. | Please recommend me some places to visit in Hong Kong including amusement parks. | 后者的推荐会更准确高效一些,但如果你想进行一些探索,那前者也能用。 |
技巧2:增加示例
结合场景2:基于示例回答,如果你无法用文字准确解释问题或指示,你可以在 Prompt 里增加一些案例:
Suggest three names for an animal that is a superhero.

Animal: Cat
Names: Captain Sharpclaw, Agent Fluffball, The Incredible Feline
Animal: Dog
Names: Ruff the Protector, Wonder Canine, Sir Barks-a-Lot
Animal: Horse
Names:
增加例子后,Output 的结果就更酷一些,或者说是接近我想要的那种风格的名字。
Gallop Guardian, Equine Avenger, The Mighty Stallion
以下是一些场景案例,我整理了两个 Less Effective(不太有效的)和 Better(更好的)Prompt,你可以自己尝试下这些案例:
| 场景 | Less Effective | Better |
|---|---|---|
| 起产品名 | Product description: A pair of shoes that can fit any foot size.Seed words: adaptable, fit, omni-fit.Product names: | Product description: A home milkshake maker Seed words: fast, healthy, compact. Product names: HomeShaker, Fit Shaker, QuickShake, Shake Maker.Product description: A pair of shoes that can fit any foot size. Seed words: adaptable, fit, omni-fit. Product names: |
| 将电影名称转为 emoji | Convert Star Wars into emoji | Convert movie titles into emoji. Back to the Future: 👨👴🚗🕒 Batman: 🤵🦇 Transformers: 🚗🤖 Star Wars: |
技巧3:使用引导词,引导模型输出特定内容
结合场景4:无中生有——写代码,有一个小技巧,场景中提到的案例,其 Prompt 还可以继续优化,在 Prompt 最后,增加一个代码的引导,告知 AI 我已经将条件描述完了,你可以写代码了。
在 Prompt 的最后增加 SELECT 可以很好地提示 AI 可以写 SQL 代码了。Better Prompt:
Create a MySQL query for all students in the Computer Science Department:
Table departments, columns = [DepartmentId, DepartmentName]
Table students, columns = [DepartmentId, StudentId, StudentName]
SELECT
同样的道理,如果你想让 AI 写 Python 代码,那 import 会是比较好的提示。但需要注意,这个只是告知 AI 可以写代码了,并不能告知 AI 写何种代码,你仍然需要在 Prompt 里增加提示,告知 AI 要生成何种语言的代码。
在吴恩达的 ChatGPT Prompt Engineering 课程中,也提到这个技巧,只是在课程中,引导词并不是放在最后,而是在 Prompt 里直接说明,让 AI 生成一个 JSON 格式的内容。课程中的例子是这样的(注意这个是 python 代码):
prompt = f"""
Generate a list of three made-up book titles along \
with their authors and genres.
Provide them in JSON format with the following keys:
book_id, title, author, genre.
"""
简单解释下,其关键是在 Prompt 里跟 AI 说明,需要 AI 按照 JSON 格式输出内容。
技巧4:增加 Role(角色)或人物
结合场景5:锦上添花——改写内容,在前面提到的改写例子,我在 Prompt 里加了 Role 让其更易于阅读,这个优化方法是 OK 的。也很常用,比如你想将你写的 Email 改得更商务,则只需要加 business 相关的词即可。
我再介绍一个更有效的技巧,就是在 Prompt 里增加一些 role(角色)相关的内容,让 AI 生成的内容更符合你的需求。
比如还是上面那个 rewrite 的例子,我在例子前加入这样的一段话,我让 AI 假设自己是一个小学老师,并且很擅长将复杂的内容转变成 7、8 岁小朋友也能听懂的话,然后再改写这段话:
You are a primary school teacher who can explain complex content to a level that a 7 or 8 year old child can understand. Please rewrite the following sentences to make them easier to understand:
Output 就变成了下面这样。不管是用词,还是语法,看起来都更容易懂了。
OpenAI is a place where people work on making computers really smart. It's like a lab where they do research to make computers do amazing things! They want the computers to be really friendly and helpful to people. They use one of the most powerful computers in the world to do this research. A bunch of really rich and smart people gave money to start this lab. One of them is Elon Musk, but he left in 2018. Another really big company, Microsoft, gave them a lot of money too.
另外除了增加角色外,还能让 AI 模拟某个人,比如让 AI 以 David Foster Wallace 的风格改写上述那段话:
Imagine you are the famous writer David Foster Wallace, please rewrite this sentences.
Output 是这样的:
As David Foster Wallace, I might rewrite these sentences to sound more like this:

OpenAI is a lab that studies something called artificial intelligence, which is like when computers can do things that normally only humans can do. They have a big computer that's one of the most powerful in the world, and they're trying to make sure the AI they create is friendly and helpful. The lab was started in 2015 in a city called San Francisco, and a bunch of important people gave them a lot of money to do their research. One of those people was Elon Musk, who stopped working there but still gives them money, and Microsoft also gave them a lot of money recently.
关于这个技巧的应用,以及如何更好地使用 AI 提升写作能力,建议各位阅读 Nat Eliason 的 Using ChatGPT as a Writing Coach,他使用 ChatGPT 辅助其写作,就用到了上述的技巧。
技巧5:使用特殊符号指令和需要处理的文本分开
结合场景7:化繁为简——信息总结,不管是信息总结,还是信息提取,你一定会输入大段文字,甚至多段文字,此时有个小技巧。
可以用 """ 将指令和文本分开。根据我的测试,如果你的文本有多段,增加 """ 会提升 AI 反馈的准确性(这个技巧来自于 OpenAI 的 API 最佳实践文档)
像我们之前写的 Prompt 就属于 Less effective Prompt。为什么呢?据我的测试,主要还是 AI 不知道什么是指令,什么是待处理的内容,用符号分隔开来会更利于 AI 区分。
Please summarize the following sentences to make them easier to understand.
OpenAI is an American artificial intelligence (AI) research laboratory consisting of the non-profit OpenAI Incorporated (OpenAI Inc.) and its for-profit subsidiary corporation OpenAI Limited Partnership (OpenAI LP). OpenAI conducts AI research with the declared intention of promoting and developing a friendly AI. OpenAI systems run on the fifth most powerful supercomputer in the world.[5][6][7] The organization was founded in San Francisco in 2015 by Sam Altman, Reid Hoffman, Jessica Livingston, Elon Musk, Ilya Sutskever, Peter Thiel and others,[8][1][9] who collectively pledged US$1 billion. Musk resigned from the board in 2018 but remained a donor. Microsoft provided OpenAI LP with a $1 billion investment in 2019 and a second multi-year investment in January 2023, reported to be $10 billion.[10]
Better Prompt:
Please summarize the following sentences to make them easier to understand.

Text: """
OpenAI is an American artificial intelligence (AI) research laboratory consisting of the non-profit OpenAI Incorporated (OpenAI Inc.) and its for-profit subsidiary corporation OpenAI Limited Partnership (OpenAI LP). OpenAI conducts AI research with the declared intention of promoting and developing a friendly AI. OpenAI systems run on the fifth most powerful supercomputer in the world.[5][6][7] The organization was founded in San Francisco in 2015 by Sam Altman, Reid Hoffman, Jessica Livingston, Elon Musk, Ilya Sutskever, Peter Thiel and others,[8][1][9] who collectively pledged US$1 billion. Musk resigned from the board in 2018 but remained a donor. Microsoft provided OpenAI LP with a $1 billion investment in 2019 and a second multi-year investment in January 2023, reported to be $10 billion.[10]
"""
另外,在吴恩达的 ChatGPT Prompt Engineering 课程中,还提到,你可以使用其他特殊符号来分割文本和 Prompt,比如<>,
text = f"""
You should express what you want a model to do by \
providing instructions that are as clear and \
specific as you can possibly make them. \
This will guide the model towards the desired output, \
and reduce the chances of receiving irrelevant \
or incorrect responses. Don't confuse writing a \
clear prompt with writing a short prompt. \
In many cases, longer prompts provide more clarity \
and context for the model, which can lead to \
more detailed and relevant outputs.
"""

prompt = f"""
Summarize the text delimited by triple backticks \
into a single sentence.
`{text}`
"""
如果你是在开发一款允许用户输入内容,并对内容进行总结的 AI 产品,那你就可以使用到这个技巧。
技巧6:通过格式词阐述需要输出的格式
结合场景8:化繁为简——信息提取,其中的案例,就是用到了这个技巧。这个技巧是技巧2:增加示例的变种,比较常用于生成文本场景。其实在场景7:化繁为简——信息总结中,你也可以用到这个技巧。
假设你想让 AI 总结一篇非常非常长的文章,并且按照特定格式给你总结,那你可以在文章前面明确输出的格式(为了不占用太多显示空间,我省略了正文内容)。它的意思其实是让 ChatGPT 按 Topic 总结,每个 Topic 里按照无序列表(就是里面那个 -)将每个 Topic 的主要观点罗列出来。
Summarize the main points of the following speech
Use the following format:
Topic 1: <topic_name_1>
- <point_1>
..
Topic 2: <topic_name_2>
- <point_1>
..
Topic 10: ..

Text: """
Thank you so much, Fred, for that lovely introduction. And thanks to the Atlantic Council for hosting me today.

The course of the global economy over the past two years has been shaped by COVID-19 and our efforts to fight the pandemic. It’s now evident, though, that the war between Russia and Ukraine has redrawn the contours of the world economic outlook. Vladimir Putin’s unprovoked attack on Ukraine and its people is taking a devastating human toll, with lives tragically lost, families internally displaced or becoming refugees, and communities and cities destroyed.
...

"""
Output 是这样的:
Topic 1: The war in Ukraine
- The war is taking a human toll with lives lost, families displaced, and communities destroyed
- The Biden administration is committed to holding Russia accountable
- The war has violated international law and is a challenge to the international order

Topic 2: The global economy
- The war is having negative impacts on the global economy, including higher commodity prices and inflation
- The IMF and World Bank will be focused on helping developing countries weather the impacts of the war
- The ultimate outcome for the global economy depends on the path of the war
关于这个场景和技巧,我想再解释一下为什么潜力很大。根据我使用各种 Summary 或者信息提取的产品,我发现,AI 并不知道什么是重点,所以在总结的过程中,会丢失很多内容。如何引导 AI 进行总结,就变得非常重要,且具有一定的可玩性。
使用此技巧可以使输出更结构化。比如针对一篇文章进行问答,你不仅想要得到一个答案,也希望 ChatGPT 的答案符合特定的格式,方便你下一步进行自动化。比如问这里的债券 duration 是多少? , 正常 GPT 模型的答案可能是债券 duration 是 4 年或duration 4 年。 ChatGPT 的回答不稳定,且不方便继续处理。
解法: 我们可以通过这个技巧,让模型理解我们预期的格式。并在此基础上,为了方便自动化,让模型输出特定的结构化答案 (比如 JSON/Markdown 等)。 也可以方便集成更多的额外要求,比如增加一个"confidence level", 并通过 Prompt 的形式指定这些数值的格式与甚至区间。比如:
{context}
Question: What is bond duration mentioned here.
Answer template (Valid JSON format):
{
"duration": $duration_numeric_value_in_year,
"confidence_level": $answer_confidence_level_high_moderate_or_low,
}}
Answer:
在吴恩达的 ChatGPT Prompt Engineering 课程中,有提到一个这个技巧的高级用法,在让 AI 按照特定格式输出内容的同时,还让 AI 根据内容是否满足特定条件,来判断应该输出什么结果,下面课程中的案例的 Prompt(注意这个是 python 代码,有一些转义字符,可以不用管):
You will be provided with text delimited by triple quotes.
If it contains a sequence of instructions, \
re-write those instructions in the following format:

Step 1 - ...
Step 2 - …
…
Step N - …

If the text does not contain a sequence of instructions, \
then simply write \"No steps provided.\"

\"\"\"{text}\"\"\"
简单解释下,这个 Prompt 分成两步: 让 AI 将输入的 text 转为步骤(就是 Prompt 里的 Step 1、2) 然后还增加了一个判断,如果输入的 text 里没有 step 的内容,那么就输出 No Step 假如输入的 text 是一个泡茶的步骤介绍:
Making a cup of tea is easy! First, you need to get some \
water boiling. While that's happening, \
grab a cup and put a tea bag in it. Once the water is \
hot enough, just pour it over the tea bag. \
Let it sit for a bit so the tea can steep. After a \
few minutes, take out the tea bag. If you \
like, you can add some sugar or milk to taste. \
And that's it! You've got yourself a delicious \
cup of tea to enjoy.
那么 AI 输出的内容是这样的(因为内容中包含了步骤式的内容):
Step 1 - Get some water boiling.
Step 2 - Grab a cup and put a tea bag in it.
Step 3 - Once the water is hot enough, pour it over the tea bag.
Step 4 - Let it sit for a bit so the tea can steep.
Step 5 - After a few minutes, take out the tea bag.
Step 6 - Add some sugar or milk to taste.
Step 7 - Enjoy your delicious cup of tea!
但如果我们输入的是这样的 text:
The sun is shining brightly today, and the birds are \
singing. It's a beautiful day to go for a \
walk in the park. The flowers are blooming, and the \
trees are swaying gently in the breeze. People \
are out and about, enjoying the lovely weather. \
Some are having picnics, while others are playing \
games or simply relaxing on the grass. It's a \
perfect day to spend time outdoors and appreciate the \
beauty of nature.
从内容上看,这段话,没有任何步骤式的内容,所以 AI 的输出是这样的:
No steps provided.
技巧7:Zero-Shot Chain of Thought
Zero-Shot Prompts
在场景1:问答问题中提到,直接提问的 Prompt ,我们称之为 Zero-shot Prompt,是一种自然语言处理技术,可以让计算机模型根据提示或指令进行任务处理。各位常用的 ChatGPT 就用到这个技术。
传统的自然语言处理技术通常需要在大量标注数据上进行有监督的训练,以便模型可以对特定任务或领域进行准确的预测或生成输出。相比之下,Zero-Shot Prompting 的方法更为灵活和通用,因为它不需要针对每个新任务或领域都进行专门的训练。相反,它通过使用预先训练的语言模型和一些示例或提示,来帮助模型进行推理和生成输出。
举个例子,我们可以给 ChatGPT 一个简短的 Prompt,比如描述某部电影的故事情节,它就可以生成一个关于该情节的摘要,而不需要进行电影相关的专门训练。
缺点
但这个技术并不是没有缺点的:
- Zero-Shot Prompting 技术依赖于预训练的语言模型,这些模型可能会受到训练数据集的限制和偏见。比如在使用 ChatGPT 的时候,它常常会在一些投资领域,使用男性的「他」,而不是女性的「她」。那是因为训练 ChatGPT 的数据里,提到金融投资领域的内容,多为男性。
- 尽管 Zero-Shot Prompting 技术不需要为每个任务训练单独的模型,但为了获得最佳性能,它需要大量的样本数据进行微调。像 ChatGPT 就是一个例子,它的样本数量是过千亿。
- 由于 Zero-Shot Prompting 技术的灵活性和通用性,它的输出有时可能不够准确,或不符合预期。这可能需要对模型进行进一步的微调或添加更多的提示文本来纠正。
技巧
基于上述的第三点缺点,研究人员就找到了一个叫 Chain of Thought 的技巧。
这个技巧使用起来非常简单,只需要在问题的结尾里放一句Let's think step by step(让我们一步步地思考),模型输出的答案会更加准确。
这个技巧来自于 Kojima 等人 2022 年的论文Large Language Models are Zero-Shot Reasoners。在论文里提到,当我们向模型提一个逻辑推理问题时,模型返回了一个错误的答案,但如果我们在问题最后加入Let's think step by step这句话之后,模型就生成了正确的答案:

论文里有讲到原因,感兴趣的朋友可以去看看,我简单解释下为什么:
- 首先各位要清楚像 ChatGPT 这类产品,它是一个统计语言模型,本质上是基于过去看到过的所有数据,用统计学意义上的预测结果进行下一步的输出(这也就是为什么你在使用 ChatGPT 的时候,它的答案是一个字一个字地吐出来,而不是直接给你的原因,因为答案是一个字一个字算出来的)。
- 当它拿到的数据里有逻辑,它就会通过统计学的方法将这些逻辑找出来,并将这些逻辑呈现给你,让你感觉到它的回答很有逻辑。
- 在计算的过程中,模型会进行很多假设运算(不过暂时不知道它是怎么算的)。比如解决某个问题是从 A 到 B 再到 C,中间有很多假设。
- 它第一次算出来的答案错误的原因,只是因为它在中间跳过了一些步骤(B)。而让模型一步步地思考,则有助于其按照完整的逻辑链(A > B > C)去运算,而不会跳过某些假设,最后算出正确的答案。
按照论文里的解释,零样本思维链涉及两个补全结果,左侧气泡表示基于提示输出的第一次的结果,右侧气泡表示其收到了第一次结果后,将最开始的提示一起拿去运算,最后得出了正确的答案:

这个技巧,除了用于解决复杂问题外,还适合生成一些连贯主题的内容,比如写长篇文章、电影剧本等。
但需要注意其缺点,连贯不代表,它就一定不会算错,如果其中某一步骤算错了,错误会因为逻辑链,逐步将错误积累,导致生成的文本可能出现与预期不符的内容。
另外,根据 Wei 等人在2022 年论文表明,它仅在大于等于 100B 参数的模型中使用才会有效。如果你使用的是小样本模型,这个方法不会生效。
而在 Yongchao Zhou 等人的最新论文中,提到了另一种更好的 Prompt ,可在 Chat 中多做尝试:
Let's work this out in a step by step way to be sure we have the right answer.
技巧8:Few-Shot Chain of Thought
Few-Shot Prompting
在技巧 2:增加示例中。提到我们可以给模型一些示例,从而让模型返回更符合我们需求的答案。这个技巧其实使用了一个叫 Few-Shot 的方法。
这个方法最早是 Brown 等人在 2020 年发现的,论文里有一个这样的例子,非常有意思,通过这个例子你应该更能体会,像 ChatGPT 这类统计语言模型,其实并不懂意思,只是懂概率。
Brown 输入的内容是这样的(whatpu 和 farduddle 其实根本不存在):
A "whatpu" is a small, furry animal native to Tanzania. An example of a sentence that uses
the word whatpu is:
We were traveling in Africa and we saw these very cute whatpus.
To do a "farduddle" means to jump up and down really fast. An example of a sentence that uses
the word farduddle is:
Output 是这样的:
When we won the game, we all started to farduddle in celebration.
不过这并不代表,Few-Shot 就没有缺陷,我们试试下面这个例子: Prompt:
The odd numbers in this group add up to an even number: 4, 8, 9, 15, 12, 2, 1.
A: The answer is False.

The odd numbers in this group add up to an even number: 17,  10, 19, 4, 8, 12, 24.
A: The answer is True.

The odd numbers in this group add up to an even number: 16,  11, 14, 4, 8, 13, 24.
A: The answer is True.

The odd numbers in this group add up to an even number: 17,  9, 10, 12, 13, 4, 2.
A: The answer is False.

The odd numbers in this group add up to an even number: 15, 32, 5, 13, 82, 7, 1.
A:
Output 是这样的:
The answer is True.
输出的答案其实是错误的,实际上的答案应该是:
Adding all the odd numbers (15, 5, 13, 7, 1) gives 41. The answer is False.
那我们有没有什么方法解决?
技巧
要解决这个缺陷,就要使用到新的技巧,Few-Shot Chain of Thought。
根据 Wei 他们团队在2022 年的研究表明:
- 通过向大语言模型展示一些少量的样例,并在样例中解释推理过程,大语言模型在回答提示时也会显示推理过程。这种推理的解释往往会引导出更准确的结果。
下面是论文里的案例,使用方法很简单,在技巧 2:增加示例的基础上,再将逻辑过程告知给模型即可。从下面这个案例里,你可以看到加入解释后,输出的结果就正确了。
 那本章节开头提的例子就应该是这样的(注:本例子同样来自 Wei 团队论文):
The odd numbers in this group add up to an even number: 4, 8, 9, 15, 12, 2, 1.
A: Adding all the odd numbers (9, 15, 1) gives 25. The answer is False.

The odd numbers in this group add up to an even number: 17,  10, 19, 4, 8, 12, 24.
A: Adding all the odd numbers (17, 19) gives 36. The answer is True.

The odd numbers in this group add up to an even number: 16,  11, 14, 4, 8, 13, 24.
A: Adding all the odd numbers (11, 13) gives 24. The answer is True.

The odd numbers in this group add up to an even number: 17,  9, 10, 12, 13, 4, 2.
A: Adding all the odd numbers (17, 9, 13) gives 39. The answer is False.

The odd numbers in this group add up to an even number: 15, 32, 5, 13, 82, 7, 1.
A:
Chain of Thought
聊完技巧,我们再结合技巧7:Zero-Shot Chain of Thought,来聊聊 Chain of Thought 的关键知识。根据 Sewon Min 等人在2022 年的研究表明,思维链有以下特点:
- "the label space and the distribution of the input text specified by the demonstrations are both key (regardless of whether the labels are correct for individual inputs)" 标签空间和输入文本的分布都是关键因素(无论这些标签是否正确)。
- the format you use also plays a key role in performance, even if you just use random labels, this is much better than no labels at all. 即使只是使用随机标签,使用适当的格式也能提高性能。
理解起来有点难,我找一个 Prompt 案例给大家解释。我给 ChatGPT 一些不一定准确的例子:
I loved the new Batman movie!  // Negative
This is bad // Positive
This is good // Negative
What a good show! //
Output 是这样的:
Positive
在上述的案例里,每一行,我都写了一句话和一个情感词,并用 // 分开,但我给这些句子都标记了错误的答案,比如第一句其实应该是 Positive 才对。但:
- 即使我给内容打的标签是错误的(比如第一句话,其实应该是 Positive),对于模型来说,它仍然会知道需要输出什么东西。换句话说,模型知道 // 划线后要输出一个衡量该句子表达何种感情的词(Positive or Negative)。这就是前面论文里 #1 提到的,即使我给的标签是错误的,或者换句话说,是否基于事实,并不重要。标签和输入的文本,以及格式才是关键因素。
- 只要给了示例,即使随机的标签,对于模型生成结果来说,都是有帮助的。这就是前面论文里 #2 提到的内容。
最后,需要记住,思维链仅在使用大于等于 100B 参数的模型时,才会生效。如果你想要了解更多相关信息,可以看看斯坦福大学的讲义:Natural Language Processing with Deep Learning
技巧9:其他
一些小的技巧,会陆续更新在这个章节
在示例里加入特定符号,让模型知道如何处理特殊情况
这个解释起来有点复杂,以下是 OpenAI 的官方 Prompt,在一些奇怪的问题上比如What is Devz9的回答,你可以用?代替答案,让模型知道当遇到超出回答范围时,需要如何处理(注意:此方法在 playground 上有效,但在 ChatGPT 上无效)。
Q: Who is Batman?
A: Batman is a fictional comic book character.

Q: What is torsalplexity?
A: ?

Q: What is Devz9?
A: ?

Q: Who is George Lucas?
A: George Lucas is American film director and producer famous for creating Star Wars.

Q: What is the capital of California?
A: Sacramento.

Q: What is Kozar-09?
A:
它的 Output 是这样的:
?